hearth-bench

“Computer, how do I build a voice assistant that doesn't send my data to the cloud?”

We asked a computer on a desk, out loud. This page is what came back, how long each part took, and what it ran on.

The answers

Each model got the question and the same instructions, with a fresh context. Shown whole, unedited.

Qwen3.6 35B-A3B · 4-bit

You can build a local voice assistant by using open-source software like Rhasspy or Mozilla DeepSpeech. These tools run entirely on your computer or a small device like a Raspberry Pi, processing audio directly without sending it to the internet. This keeps your voice data private and secure within your own home network.

124 ms to first word0.75 s in all83.0 tokens/s

Gemma 4 26B-A4B · 6-bit

To build a private assistant, you should look into running large language models locally on your own hardware. You can use open source tools like Ollama or LocalAI to handle the processing without an internet connection. You will also need a local speech to text engine to process your voice commands.

160 ms to first word1.16 s in all50.2 tokens/s

Qwen3.8 27B · 6-bit

You can run open source speech recognition and text to speech models locally on your own machine. Tools like Whisper for speech to text and Piper for text to speech work offline. Pair them with a local large language model like Llama or Mistral for the assistant brain. This keeps all your audio and text on your hardware.

187 ms to first word3.29 s in all19.8 tokens/s

Phi-4 mini · 4-bit

To build a voice assistant that doesn't send your data to the cloud, you can use local processing. This means running the assistant on your device, like a smartphone or a computer, without sending data to external servers. You'll need to develop or use existing software that can process voice commands locally. Keep in mind that this approach may limit some features and may not be as secure as cloud-based solutions. Always ensure you're following best practices for data privacy and security.

247 ms to first word6.33 s in all14.5 tokens/s
The instructions every model got

You are a voice assistant. Everything you write is read aloud by a text-to-speech engine to a person who is listening, not reading. Keep replies short and conversational: two to four sentences, in plain spoken English. No lists, headings, markdown, emoji or code. Spell out anything a voice cannot say. If the person wants more detail, they will ask.
The pictures

One prompt, one seed, every image model. The time is for one image from a model that is already loaded.

Z-Image

48.5s per image
1024 × 1024 pixels · model already loaded · first request took 63.2 s
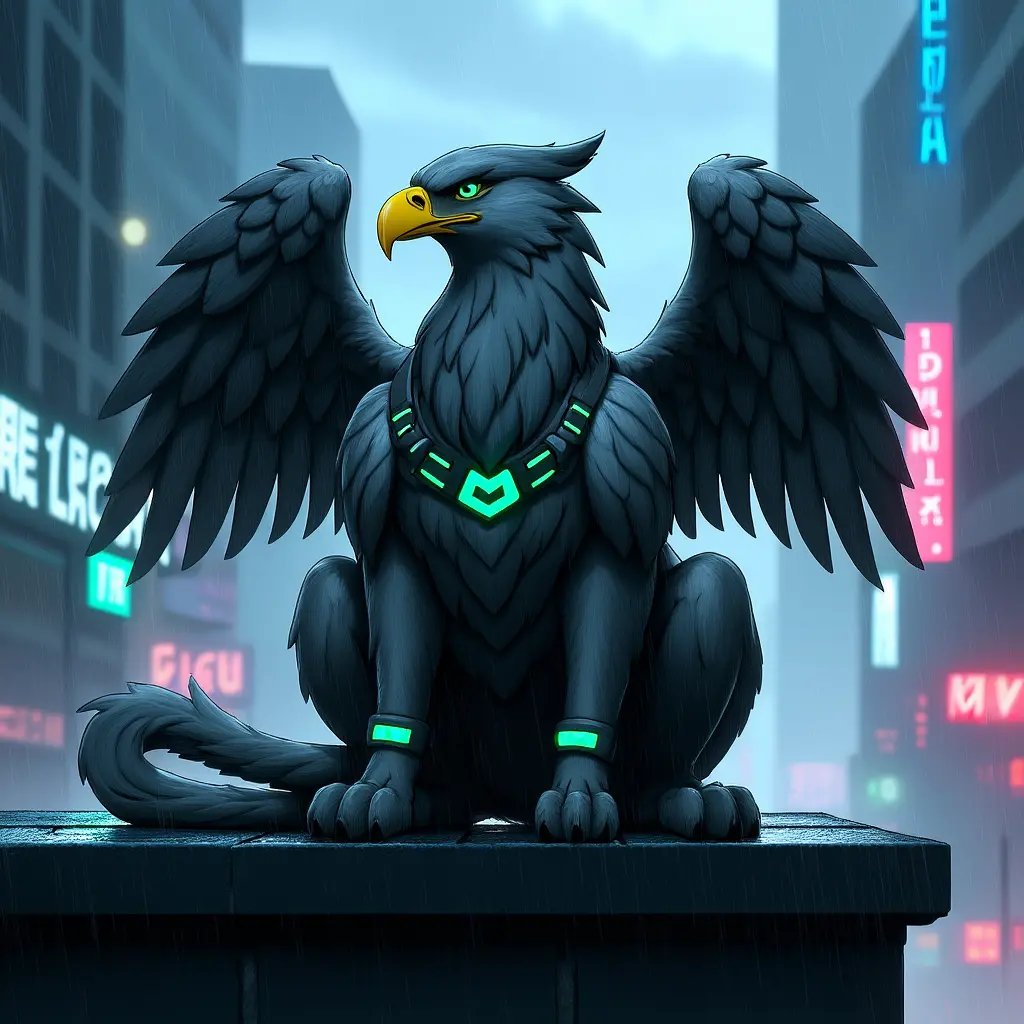
Z-Image: its picture for the prompt below

FLUX.2 Klein 9B

5.4s per image
1024 × 1024 pixels · model already loaded · first request took 28.7 s
Image not shown: the model's licence terms do not allow it here.

OmniGen2

53.1s per image
1024 × 1024 pixels · model already loaded · first request took 92.3 s
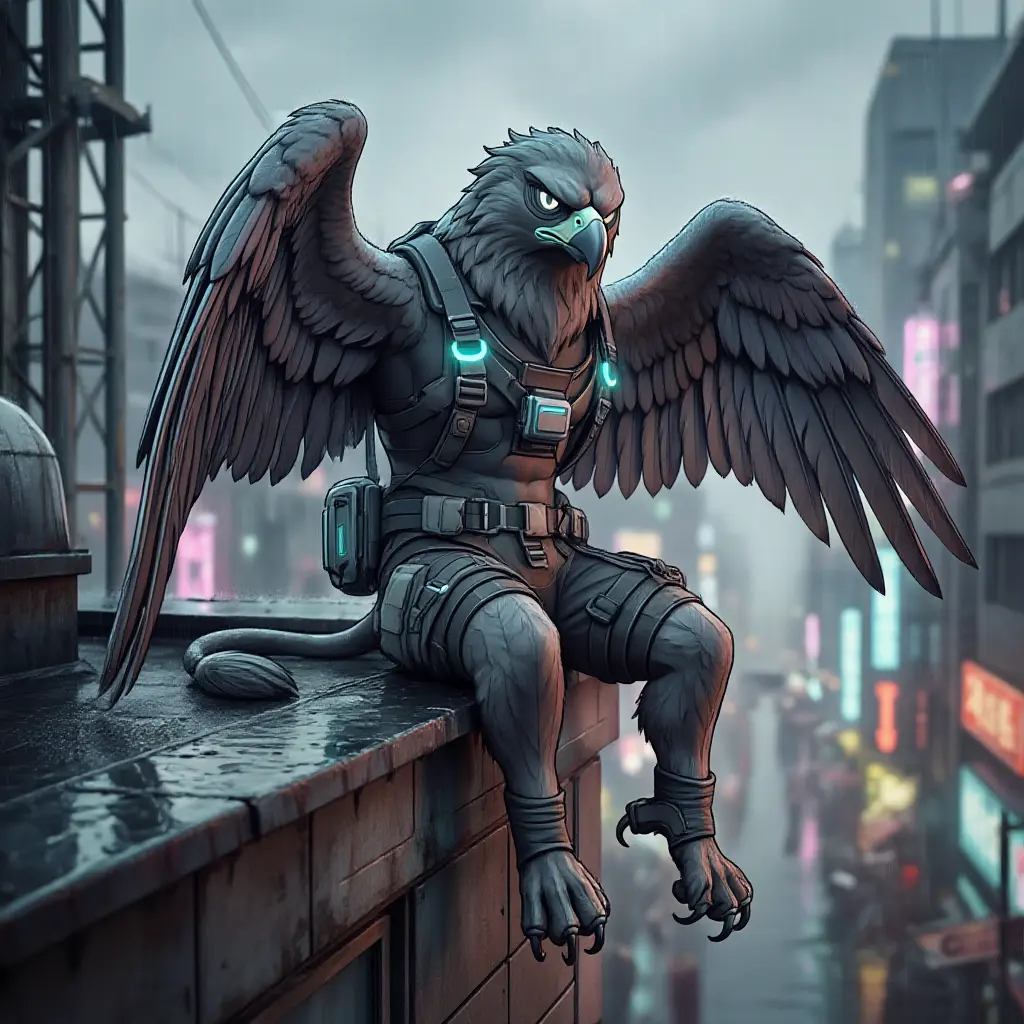
OmniGen2: its picture for the prompt below
The prompt

Tech-junkie poster, metal industrial animated style. Sharp, almost photo-realistic textures. A griffin, all gray, with head, beak and wings of an eagle with the powerful legs and tail of a lion. The wings extend out from his sides, showing flowing dark rows of feathers in 3 shades of gray. His eyes are glowing grey with cyan light. He is wearing a saddle, small compared to his size, held on with tactical utility straps with glowing cyan neon accents. He is sitting on a rain-slicked rooftop ledge, resting back on his hind legs, looking directly at the viewer with a challenging, questioning gaze. Gritty neo-Tokyo background, soft bokeh of neon lights, heavy rain, moody dramatic rim lighting, volumetric fog. No title. Only visible text is on street signs.

Hear it

Qwen3.8 27B's answer, read by Kokoro in 6 voices.

You can run open source speech recognition and text to speech models locally on your own machine. Tools like Whisper for speech to text and Piper for text to speech work offline. Pair them with a local large language model like Llama or Mistral for the assistant brain. This keeps all your audio and text on your hardware.

Locally Running Services

Everything on this tab came from these, running on the machine itself with no call to an outside API. Each one is open source: follow a link and run it.

LLM
OpenAI API via llama-swap ↗

llama.cpp servers behind a model-swapping proxy. A 35B-A3B model at 4-bit answers by default.

OpenAI API via OpenVINO Model Server ↗

Phi-4 mini at 4-bit.

TTS
Kokoro-FastAPI ↗

Kokoro, 82M parameters, with an OpenAI-style speech endpoint.

Image Gen
OpenAI API via llama-swap ↗

Z-Image, FLUX.2 Klein and OmniGen2, each behind the same proxy.

The command behind this tab
hearthbench showcase --config config/showcase.yaml --out-dir DIR

Where the time goes in one spoken turn

Asked aloud: “Computer, how do I build a voice assistant that doesn't send my data to the cloud?” The clock stops at the first audio of the reply.

Hobby

0 s1 s2 s3 s4 sEnd-of-turn silenceEnd-of-turn silence: 0 to 1805 ms1,805 msSpeech to textSpeech to text: 0 to 588 ms588 msAgent (stand-in)Agent (stand-in): 1805 to 2309 ms504 msText to speechText to speech: 2309 to 3833 ms1,524 msfirst audio 3.83 s

Developer

0 s1 s2 s3 s4 sEnd-of-turn silenceEnd-of-turn silence: 0 to 1807 ms1,807 msSpeech to textSpeech to text: 0 to 528 ms528 msAgent (stand-in)Agent (stand-in): 1807 to 2317 ms510 msText to speechText to speech: 2317 to 2580 ms263 msfirst audio 2.58 s

Side by side

Means over the timed turns.

metricHobbyDeveloper
Speech to text600ms
522ms
Text to speech, to first audio1,581ms
290ms
Machine at workspeech to text + agent's first words + text to speech2,184ms
817ms
Turn closed → first audio2,087ms
800ms
Question asked → first audio3,892ms
2,606ms

Every stage, every setup

Full statistics and the settings each run used.

Hobby

stagemean msp50p95minmaxn
Speech to text60060161557861912
End-of-turn silence (a setting)1,8041,8051,8051,8031,80512
Agent stand-in, first words2.82.73.81.34.112
Agent stand-in, first sentence complete (scripted)50350450450250512
Text to speech, to first audio1,5811,5261,8151,5091,86812
Turn closed → first audio2,0872,0302,3222,0162,37312
Question asked → first audio3,8923,8354,1273,8214,17812
Turns timed
12 of 12, after 1 thrown away
Question clip
synthesized by this setup's TTS, voice am_eric, 4.47 s
End-of-turn silence
1.8 s
Agent
voiceloop-agent: a scripted stand-in, no LLM. It sends its reply in two halves 0.5 s apart, so the first sentence completes 0.5 s after it starts.
Clock
this process, at the moment each event is observed
Events of the charted turn
event of the charted turnms
chunk_received0.0
user_start587
user_text588
user_stop1,805
agent_start1,806
agent_text1,806
agent_text2,308
agent_stop2,309
tts_request2,309
audio3,833

Developer

stagemean msp50p95minmaxn
Speech to text52252352851252812
End-of-turn silence (a setting)1,8061,8061,8071,8051,80712
Agent stand-in, first words5.25.25.54.95.512
Agent stand-in, first sentence complete (scripted)50550550550450512
Text to speech, to first audio29026440825852312
Turn closed → first audio8007749187671,03312
Question asked → first audio2,6062,5802,7242,5732,83812
Turns timed
12 of 12, after 1 thrown away
Question clip
synthesized by this setup's TTS, voice am_eric, 4.49 s
End-of-turn silence
1.8 s
Agent
voiceloop-agent: a scripted stand-in, no LLM. It sends its reply in two halves 0.5 s apart, so the first sentence completes 0.5 s after it starts.
Clock
this process, at the moment each event is observed
Events of the charted turn
event of the charted turnms
chunk_received0.0
user_start526
user_text528
user_stop1,807
agent_start1,810
agent_text1,812
agent_text2,315
tts_request2,317
agent_stop2,318
audio2,580

What this does not say

  • The clock starts with the whole question in hand. Microphone capture and the voice detector's closing silence are not in it.
  • The agent is a scripted stand-in, not a language model. Its amber bar is a fixed pause; a real model's time to a first sentence would take its place.
  • The grey bar is a wait the voice loop is set to make, the same on every setup. Transcription runs inside it.
  • Each chart draws the turn whose total was the median.

Locally Running Services

Everything on this tab came from these, running on the machine itself with no call to an outside API. Each one is open source: follow a link and run it.

STT
Whisper-STT ↗

Whisper small.en at 8-bit, on OpenVINO GenAI.

TTS
Kokoro-FastAPI ↗

Kokoro, 82M parameters, with an OpenAI-style speech endpoint.

The command behind this tab
hearthbench --services SETUP.yaml e2e --iterations 12 --merge-into RESULT.json

Language model

Streamed chat completions. First-token time is from the request; decode speed counts tokens after the first.

metricHobbyDeveloper
Modelphi4-int4-ovqwen3.6-35b-a3b:Q4_K_P
KV cachecontext the server holdsgrows as needed (cache_size 0), up to 256 sequences262,144 tokens, one cache shared by 8 slots
Decode speedhigher is better15.4tok/s
99.7tok/s
First tokenlower is better382ms
197ms
First word of the answerlower is better; after any reasoning382ms
197ms
Full statistics and every run

Hobby

timingmean msp50p95minmaxn
First token of any kind38238339535839712
First token of the answer38238339535839712
Model served as
Phi-4-mini-instruct-int4-ov
Tokens per run
128
Runs that never reached an answer
0
Every run (12)
runfirst token msfirst answer mswall mstokenstokens/s
13583584,07858.015.6
23853854,42863.015.6
33823828,65012515.1
43813814,09258.015.6
53723724,45263.015.4
63853858,66012515.1
73973974,12358.015.6
83813814,44563.015.5
93833838,74912514.9
103903904,15958.015.4
113933934,45163.015.5
123763768,64112515.1

Developer

timingmean msp50p95minmaxn
First token of any kind19719826413027812
First token of the answer19719826413027812
Model served as
qwen3
Tokens per run
128
Runs that never reached an answer
0
Every run (12)
runfirst token msfirst answer mswall mstokenstokens/s
113013061347.097.3
22782781,58212898.1
32132131,50512899.0
413613660647.0100.0
52532531,53412899.9
61961961,473128100
713713760247.0101
82542541,53712899.8
91921921,48012899.3
1013613660247.0101
112462461,527128100.0
121991991,475128100

Speech to text

Fixed clips, each sent whole. Speed is audio length over wall time.

metricHobbyDeveloper
Speedhigher is better7.9× real time
9.3× real time
One clip, request to transcriptlower is better462ms
392ms
Word error ratelower is better; clean test clips0.000
0.000
Full statistics and every run

Hobby

timingmean msp50p95minmaxn
One clip, request to transcript46245549344049812
Every run (12)
runwall msaudio sRTFWER
14423.50.1280.000
24693.70.1270.000
34983.70.1330.000
44463.50.1290.000
54883.70.1320.000
64513.70.1210.000
74503.50.1300.000
84803.70.1290.000
94463.70.1190.000
104403.50.1270.000
114773.70.1290.000
124593.70.1230.000

Developer

timingmean msp50p95minmaxn
One clip, request to transcript39238641337641512
Every run (12)
runwall msaudio sRTFWER
13843.50.1110.000
24153.70.1120.000
33903.70.1040.000
43863.50.1120.000
54123.70.1110.000
63823.70.1020.000
73783.50.1090.000
84093.70.1100.000
93863.70.1030.000
103783.50.1090.000
114083.70.1100.000
123763.70.1010.000

Text to speech

Fixed sentences. First byte is when audio starts arriving.

metricHobbyDeveloper
Speedhigher is better2.4× real time
27.6× real time
First audio bytelower is better1,495ms
132ms
Full statistics and every run

Hobby

timingmean msp50p95minmaxn
Request to first audio byte1,4958194,8097556,10012
Voice
af_bella
Speaking rate
1.1
Every run (12)
runfirst byte mswall msaudio scharactersRTF
17687693.561.00.222
26,1006,1003.766.01.6
33,7533,7533.766.01.0
47557553.561.00.219
58638633.766.00.233
67787783.766.00.208
77727733.561.00.223
88358363.766.00.226
98038043.766.00.215
108018023.561.00.232
118548553.766.00.230
128528533.766.00.228

Developer

timingmean msp50p95minmaxn
Request to first audio byte13211619811327012
Voice
af_bella
Speaking rate
1.1
Every run (12)
runfirst byte mswall msaudio scharactersRTF
12702713.561.00.078
21391413.766.00.038
31331333.866.00.035
41131133.561.00.033
51171173.766.00.032
61171183.866.00.031
71151163.561.00.033
81151153.766.00.031
91151153.866.00.031
101181183.561.00.034
111151153.766.00.031
121141143.866.00.030

Embeddings

One passage at a time, then a small batch.

metricHobbyDeveloper
One passagelower is better–44.0ms
Batchedhigher is better–55vectors/s
Full statistics and every run

Developer

timingmean msp50p95minmaxn
One passage44.032.290.621.790.912
Model served as
qwen3-embed
Vector size
1024

The setups

The config each run was given, as the result file recorded it, with credentials removed.

Hobby

Measured
2026-10-12
Architecture
x86_64
hearth-bench commit
not recorded
Result schema
0.2.0
args:
  iterations: 12
  max_tokens: 128
llm:
  base_url: http://127.0.0.1:4444/v3
  model: Phi-4-mini-instruct-int4-ov
  verify_tls: true
embeddings:
  base_url: http://127.0.0.1:4443/v1
  model: nomic-embed-text:latest
  verify_tls: true
stt:
  url: http://127.0.0.1:8080
tts:
  url: http://127.0.0.1:8880
  voice: af_bella
  speed: 1.1
agent:
  url: http://127.0.0.1:4500
judge:
  base_url: http://127.0.0.1:4444/v3
  model: Phi-4-mini-instruct-int4-ov
  verify_tls: true

Developer

Measured
2026-10-12
Architecture
x86_64
hearth-bench commit
not recorded
Result schema
0.2.0
args:
  iterations: 12
  max_tokens: 128
llm:
  base_url: http://127.0.0.1:8000/v1
  model: qwen3
  verify_tls: true
  extra_body:
    chat_template_kwargs:
      enable_thinking: false
embeddings:
  base_url: http://127.0.0.1:8000/v1
  model: qwen3-embed
  verify_tls: true
stt:
  url: http://127.0.0.1:8080
tts:
  url: http://127.0.0.1:8880
  voice: af_bella
  speed: 1.1
agent:
  url: http://127.0.0.1:4500
judge:
  base_url: http://127.0.0.1:8000/v1
  model: qwen3
  verify_tls: true

What this does not say

  • Each column is one result file from one machine. Run-to-run spread is in the statistics; machine-to-machine spread is not.
  • Speech-to-text accuracy is scored on a handful of clean clips. A word error rate of zero says the model is wired correctly, not that it is perfect.
  • A setup is one chosen configuration. Nothing here says it is the best one for its hardware.
  • Hobby: embeddings: unavailable at discovery, component skipped
  • Hobby: scoring: not run (use `hearthbench score`, it's slow/judge-cost-bearing)
  • Developer: scoring: not run (use `hearthbench score`, it's slow/judge-cost-bearing)

Locally Running Services

Everything on this tab came from these, running on the machine itself with no call to an outside API. Each one is open source: follow a link and run it.

LLM
Hobby
OpenAI API via OpenVINO Model Server ↗

Phi-4 mini at 4-bit.

Developer
OpenAI API via llama-swap ↗

llama.cpp servers behind a model-swapping proxy. A 35B-A3B model at 4-bit answers by default.

STT
Whisper-STT ↗

Whisper small.en at 8-bit, on OpenVINO GenAI.

TTS
Kokoro-FastAPI ↗

Kokoro, 82M parameters, with an OpenAI-style speech endpoint.

Embeddings
OpenAI API via llama-swap ↗

A 0.6B embedding model at 8-bit, on the same proxy.

The command behind this tab
hearthbench --services SETUP.yaml run --iterations 12 -o RESULT.json